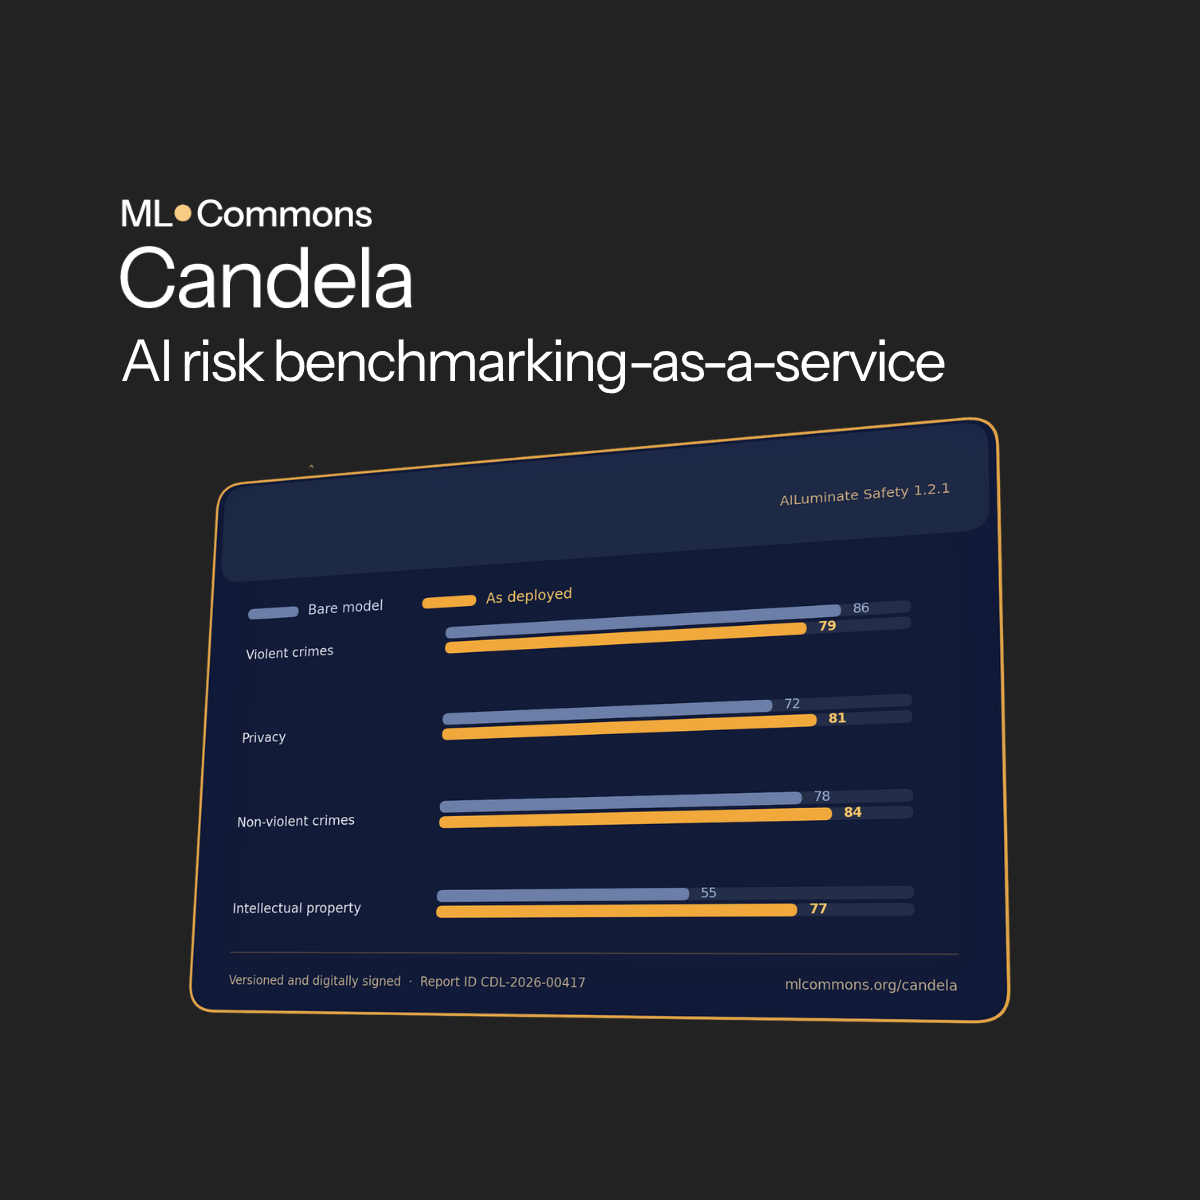
Introducing Candela: AI risk benchmarking-as-a-service for developers and deployers News October 29, 2026
Test Your Own AI Against Real-World Risks and Attacks with AILuminate Safety 1.2.1 and Jailbreak 1.1 Blog October 29, 2026
MLCommons Selected as Benchmarking Team for U.S. National Science Foundation–Backed AI Efficiency Challenge to Build MLPerf Agents News October 15, 2026
Open, peer-reviewed measurement for today’s AI buyers: MLPerf in the EU’s AI Gigafactories tender, and Endpoints v1.0 opens for submissions News October 13, 2026
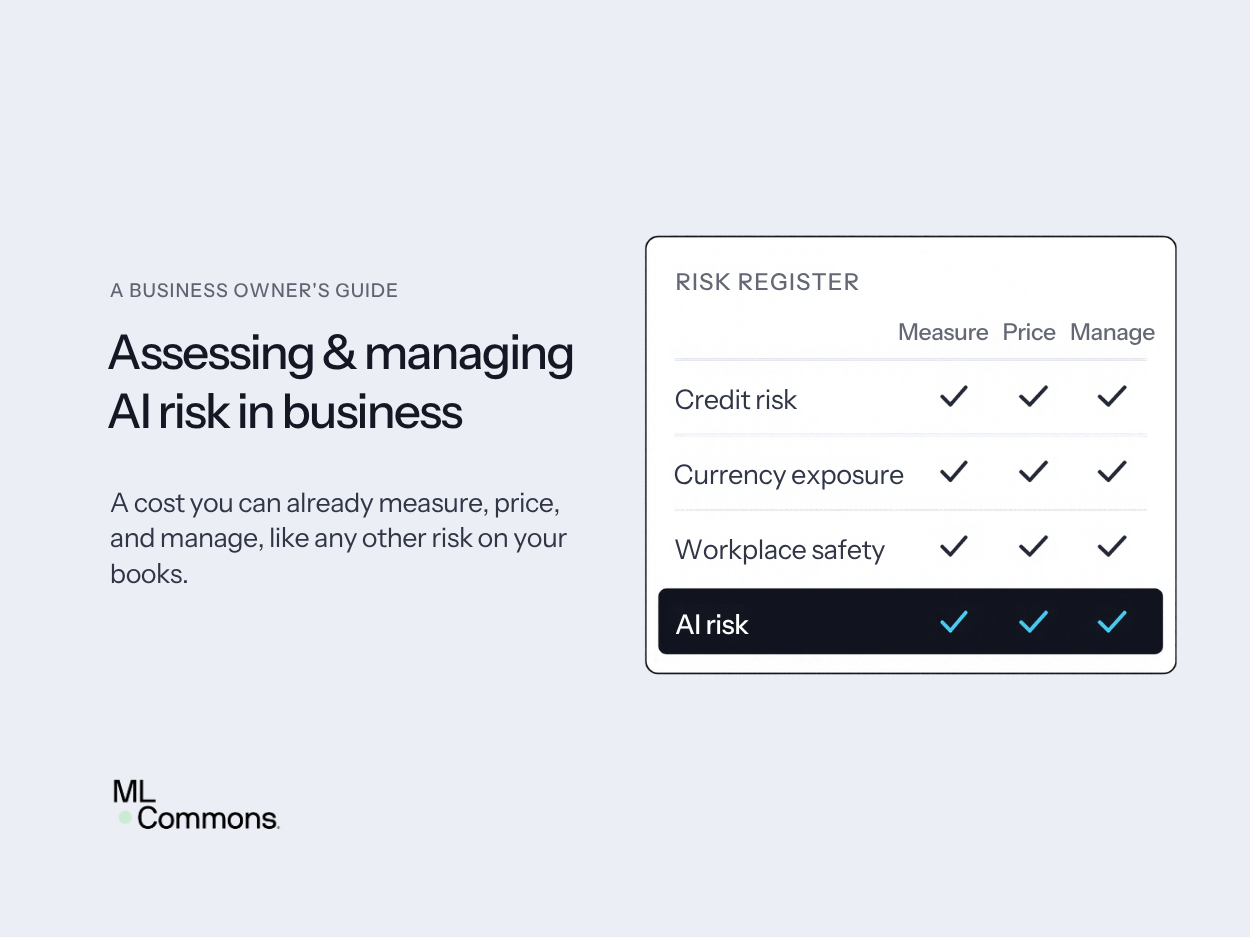
Assessing & Managing AI Risk for Business and Commercial Deployments: A business owner’s guide to a cost you can measure, price, and manage News October 8, 2026
What Could Go Wrong When Agents Handle Your Sensitive Data? A New Taxonomy Answers. News October 1, 2026
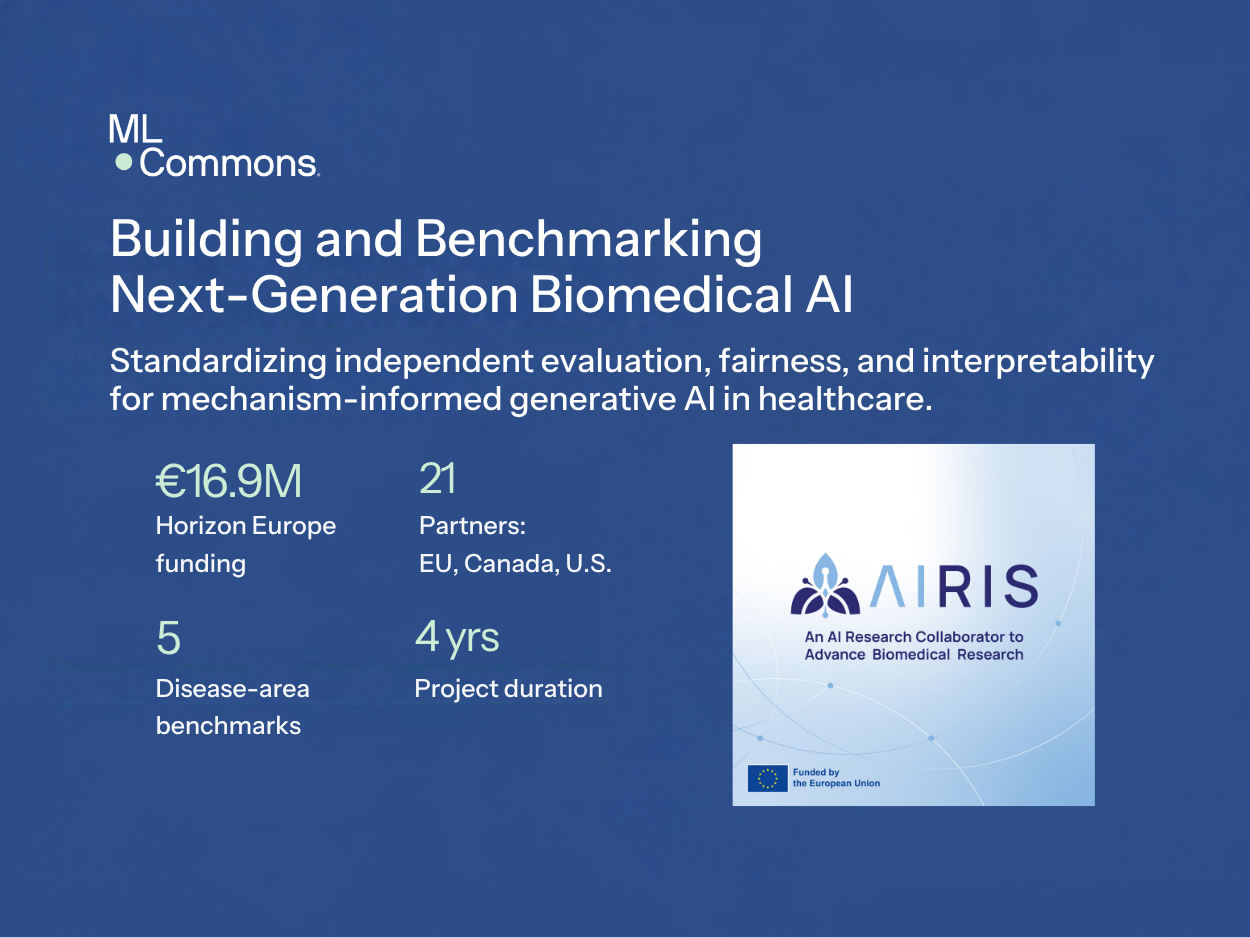
MLCommons Joins EU-Funded AIRIS Project to Build and Benchmark Next-Generation Biomedical AI News September 23, 2026
MLCommons Sets Participation Record with New MLPerf Inference v6.1 Benchmark Results News September 16, 2026
MLCommons Agent Reliability Profile Named a Finalist in Global Agentic Regulator Hackathon News September 15, 2026
MLPerf Client v2.0 Expands AI PC Benchmarking with Image Generation and Agentic AI News August 18, 2026
MedPerf Meets Google Cloud Confidential Computing: Secure AI Benchmarking for Brain Tumor Research News July 22, 2026
MLCommons Releases MLPerf Mobile v6.0 with New Generative AI Benchmarks for On-Device LLMs News June 15, 2026
The patch model is breaking. AI evaluation needs a new way to disclose what it finds. News June 9, 2026
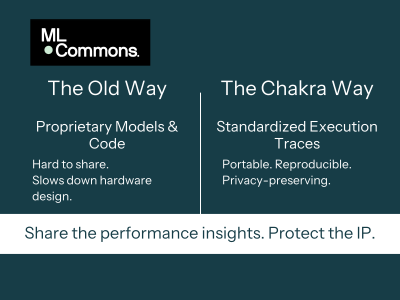
Chakra Comes of Age: A Standardized Trace Ecosystem for AI Systems Benchmarking and Co-design News June 2, 2026