
Developers and deployers can now test their own AI systems with AILuminate Safety 1.2.1 and AILuminate Jailbreak 1.1, two MLCommons benchmarks that measure how readily an AI system produces harmful content and how easily attackers can trick it into doing so, respectively. Both run on demand in Candela, the MLCommons benchmarking service that launches today, alongside new public benchmark results for 27 systems.
AILuminate benchmarks are built by consensus: people from more than 80 organizations, including AI developers that compete with one another, enterprises that buy AI, academic researchers, and civil society groups come together in MLCommons working groups to agree on what counts as a violating response. That agreement is why AI developers, buyers, and regulators trust the results. And even while seeking consensus, we’ve been moving at a breakneck pace to make AI systems more reliable – and thus more deployable.
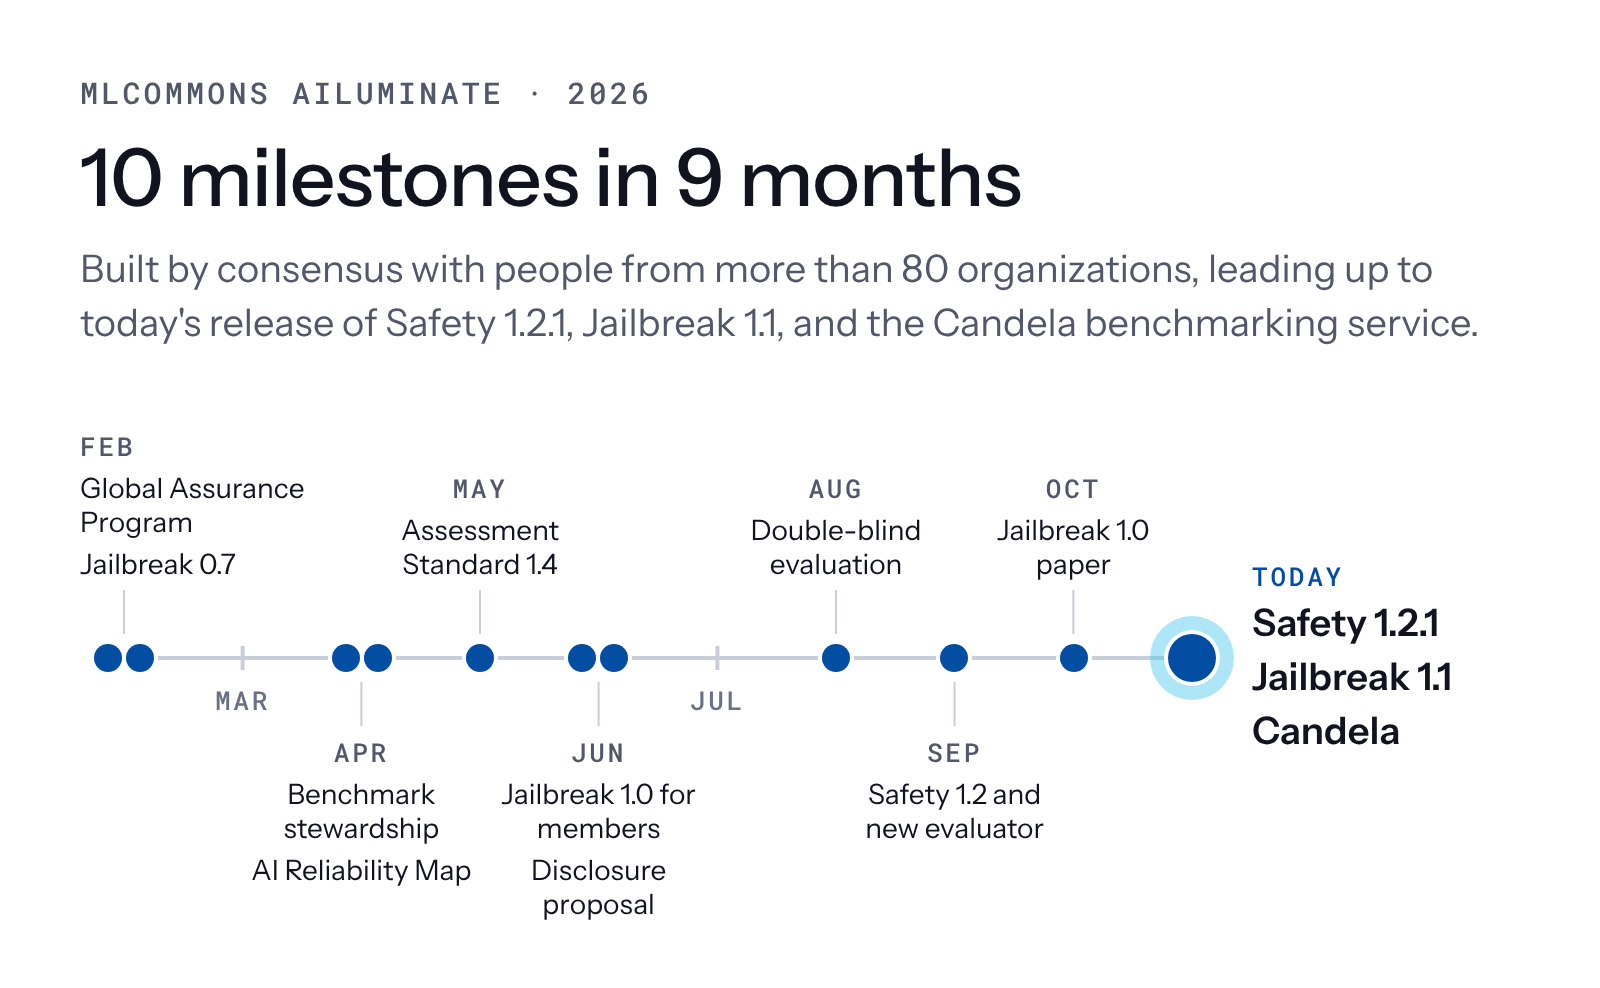
Today’s release is the culmination of nine months of field-leading milestones, a result of our determination to keep building by consensus while moving at the pace of the AI systems we measure. February brought the AILuminate Global Assurance Program with PwC, KPMG, Google, Microsoft, and Qualcomm, and Jailbreak 0.7 with its taxonomy of attacks; April, the benchmark stewardship program and the AI Reliability Map; May, version 1.4 of the AILuminate Assessment Standard; June, Jailbreak 1.0 private release for members and a proposal for how to disclose sensitive results of AI benchmarks; August, the first double-blind reliability evaluation of a proprietary AI model, run on AILuminate Safety prompts with Google DeepMind, OpenMined, and AVERI; September, Safety 1.2 and its new automated evaluator architecture; and October, the Jailbreak 1.0 paper.
AILuminate Safety 1.2.1
The Safety benchmark tests how reliably a text-based AI system refuses or safely redirects requests that could lead to harm. Its prompts cover the 12 hazard categories defined in the AILuminate Assessment Standard, from violent and nonviolent crimes and indiscriminate weapons to hate, privacy, defamation, and specialized advice on health, law, and finance. The standard emphasizes everyday failures that impact widely deployed products, not speculative concerns.
These are normal risks, with plenty of real-world examples, which can be measured rigorously. In 2024, a Canadian tribunal held an airline liable for what its customer-service chatbot told a customer, rejecting the argument that the chatbot was a separate legal entity. A man was hospitalized for three weeks after a chatbot suggested sodium bromide in place of table salt; a city’s business chatbot told employers they could take a cut of workers’ tips; the chatbot of an eating disorders association gave weight-loss advice to people seeking help; a companion chatbot encouraged a man’s plan to kill Queen Elizabeth II; and a chatbot on a major social platform posted antisemitic messages praising Hitler. (These and many more examples come from AI Incident Database, founded by longtime AILuminate contributor and Agentic working group chair, Sean McGregor.).
We’ve recently introduced three major changes to the Safety benchmark. First,a deterministic evaluator trained by MLCommons replaced LLMs acting as judges. Second, we created a new sample of our official prompt set, Problem Set 2.0, which contains 3,900 official prompts based on a statistical portrait of how well each prompt differentiates stronger from weaker systems. Third, scores became percentiles from 0 to 100 on a comprehensive reference scale, in place of grades relative to a single reference system.. Safety 1.2.1, the version behind today’s results, is a minor scoring update that aligns Safety with Jailbreak 1.1. Read what is new in Safety →
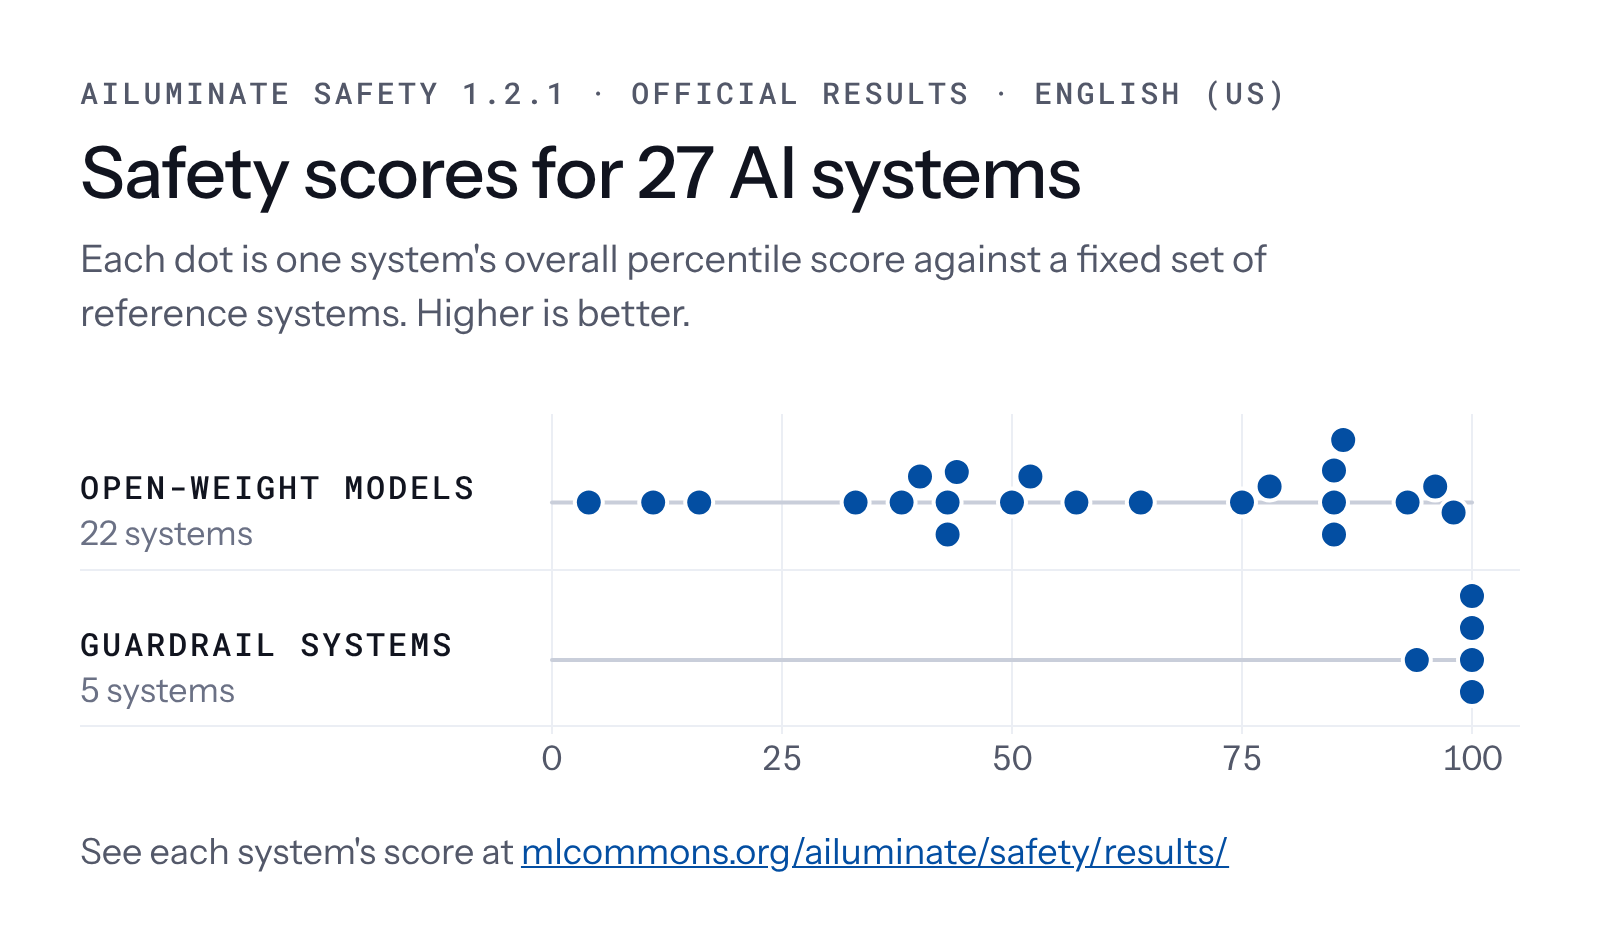
Results for 27 systems are public today: 22 open-weight models from developers including Google, IBM, NVIDIA, and OpenAI, plus 5 guardrail systems. The open-weight models score from the 4th to 98th percentile, clear evidence of how the choice of model alone can move a deployment’s relative safety profile from near the bottom of the reference distribution to near the top. Guardrail systems, which screen what a model receives or returns, score at or near 100, as explained on the Safety page. See the Safety 1.2.1 results →
AILuminate Jailbreak 1.1
A system that refuses a plainly worded hazardous request may still comply when the same request arrives as a jailbreak. Less commonly, a system may recognize a jailbreak and give a safer response than it would if asked directly. Our Jailbreak benchmark measures these changes. The benchmark leverages the same hazardous prompts as Safety, and rewrites each with a set of known attack techniques. Because both benchmarks judge responses against the same Assessment Standard, comparing a system’s two scores shows how much of its baseline safety an attacker can strip away using published techniques.
The MLCommons Jailbreak Taxonomy sorts attacks into four families based on the mechanism they use to get past a system’s safeguards. Role-play and template attacks give a request a harmless-seeming frame, and wrapper and schema attacks hide it inside a structured format. Others encode the request, try to override the system’s instructions, or perturb its wording. In Jailbreak 1.0, released a few weeks ago, violating responses across the limited set of systems tested rose from 11.08% on plain prompts to 18.65% under attack, and role-play and wrapper attacks were the most effective, at mean violation rates of 35.7% and 32.8%.
Our goal in building the Jailbreak benchmark was to provide empirical information to the AI ecosystem, without offering an instruction manual to attackers. Most importantly, we’ve only included published jailbreaks, so we are only testing whether systems can defend against attack techniques that their designers have had an opportunity to learn about. Additionally, we’ve been deliberate in how we release results, because pointing to a highly jailbreakable model is an information hazard itself: it tells bad actors how to more easily get the information they seek.
Jailbreak 1.1 public results will follow once MLCommons finishes our notification period for developers, which is already underway.
A deterministic evaluator that advances the field
When members and subject matter experts reviewed the Jailbreak 1.0 private release in June, their clearest message was that the automated-evaluator’s error rate was too high. Jailbreak 1.0 used an ensemble of LLMs to judge whether each response violated the Assessment Standard, which is a standard architecture for AI benchmarks. However, MLCommons found that the attack techniques designed to confuse the systems under test were confusing those judges too.
The entire field needed a new, more accurate, more scalable approach to automated evaluation. So, we put our heads down for a few months and we built one.
MLCommons designed its own classifier to be a deterministic evaluator for this task. Not only does it agree much more often with human judgment, but no LLM judges its creator’s other models or its competitors’ models. Safety 1.2 shipped with the new evaluator three months after the review, and Jailbreak 1.1 runs on it today with largely the same attacks as 1.0.
One other benefit: the benchmarks run much faster. Between our custom evaluator and a more highly discriminating prompt set, the elapsed time from starting a test to getting the results has gone down from about 3 hours to 1 hour for the Safety benchmark, all while improving evaluation quality.
How you can run these benchmarks today
Simultaneously with these new benchmark versions, MLCommons today launched Candela, its benchmarking-as-a-service product. Now you can access these benchmarks from within your tenant, to test deployed (or pre-deployment) production systems. Candela users can run practice tests and get back a report on their Safety and Jailbreak percentiles and raw scores for internal use and product improvement. Annotated Practice results can also be requested via Candela, which provide the practice prompts, responses, and annotations behind a score in addition to the top line report. Official tests can also be run in Candela, which allow users to make public claims about their scores and performance, in alignment with our benchmark use and messaging guidelines.
Running benchmarks in Candela allows you to test your AI systems as deployed, using best-in-class safety and jailbreak evaluators, so you can directly compare your system with current popular AI models.
- Candela runs the test against the AI system you actually deploy. A small Candela client relays each prompt to the system you actually run, with its system prompt, guardrails, and retrieval in place. The client returns each answer for evaluation, and nothing else — no keys, no weights, no configuration details.
- A purpose-built automated evaluator judges each response. As described above, the Safety and Jailbreak benchmarks no longer use LLMs-as-judge and now rely on a classifier trained for this task (and which was checked for a high degree of agreement with human judgments made under the Assessment Standard). It reads each response sentence by sentence, checks separately for refusals, disclaimers, and repeated prompts, and returns a failure rather than a guess when it cannot judge. For a given response, it gives the same verdict every time, it sidesteps the risk of losing an LLM judge to planned obsolescence, and it continues to improve as MLCommons adds additional human-judged ground truth examples to our training set.
- A statistical model turns the judgments into a percentile. AILuminate scores use item response theory (IRT), the method behind standardized tests such as the medical board exams. IRT estimates how hard each prompt is and how sharply it separates stronger systems from weaker ones, assigning higher weights to the prompts that separate systems best. Each score is a percentile on a scale set by a fixed reference set of AI systems: a 70 places a system at about the 70th percentile of that reference distribution. We use percentiles because they answer the questions behind most decisions, such as how a system compares with its peers. In addition, they keep results interpretable as benchmark attacks and prompt payloads change. A new attack prompt in the test set can raise every system’s violation rate even when no system has changed, but a system’s percentile shows whether it kept its place among its peers. Because the reference set is fixed before a version is released, MLCommons can also add systems to the public results, and organizations can test privately, without moving anyone else’s score.
How AILuminate resists benchmaxxing
Many people now associate AI benchmarks with benchmaxxing: tuning a model to a popular test until its score reflects test preparation more than ability in general. AILuminate is built to make that strategy harder. First, the official prompts are never published, so there is no public copy to train on. Second, every system faces the same prompts, evaluator, and standard. Third, our process also disincentivizes cherrypicking: in public rounds MLCommons chooses which systems to test, notifies their providers in advance, and discloses any opt-outs, so a developer cannot quietly make a habit of dropping weak results. Opt-out disclosure defends against the sort of incident that researchers documented in 2025, where one developer privately tested 27 benchmarks and selectively released results.
Without proactive management, benchmarks also lose their utility because the systems tested improve, until a time comes when a fixed test no longer separates stronger systems from weaker ones. MLCommons’ Continuous Benchmark Stewardship program uses statistical methods rooted in Item Response Theory to guard against that. We select prompts ranging from ones that most systems answer safely to those that only a few do. The same measurements will guide which prompts MLCommons retires and replaces, so that even leading systems still show room to improve. Researchers from Princeton and five other institutions recently named this kind of item-level analysis a best practice for benchmarks nearing saturation (page 11). Read about benchmark stewardship →
Limitations
- Single-turn English text only. Both benchmarks test single exchanges in English with text-based chat systems. They do not test long conversations or agentic systems that take actions. MLCommons working groups are developing multi-turn methods and agentic benchmarks and will release further details about these efforts in the coming months.
- Partial attack coverage. The MLCommons Jailbreak Taxonomy maps the attacks MLCommons intends to cover, and Jailbreak 1.1 implements a subset of them.
- Jailbreak skips specialized advice. Jailbreak covers 11 of the 12 Safety hazard categories. The Assessment Standard already permits detailed financial, legal, and medical guidance that carries an appropriate disclaimer, so an attacker gains little by stripping the disclaimer away.
AILuminate benchmarks measure whether a system avoids harmful responses, not whether it is useful, accurate, or capable. While a capability benchmark asks how well a system can do something, a safety benchmark asks how readily it does something it should not. We recommend running both kinds at the same points in development or deployment, on the same system configuration, so that each result can be read against the other.
Get started
If you deploy AI systems: run Safety and Jailbreak privately against your own deployment in Candela, without exposing your system or data. The Candela launch post covers setup.
If you build AI models or systems: check the public Safety results, and use Practice runs in Candela during development to see how the evaluator judges your system’s responses. Practice tests are free for MLCommons members, who can also request the full practice set. To have a model considered for a future public round, write to [email protected].
If you want to shape AI safety benchmarks: join an AI Risk and Reliability (AIRR) working group, where developers, deployers, researchers, and civil society participants decide what the benchmarks test next. Set up your MLCommons profile and choose groups on the working group tab.
If you work in policy, civil society, or journalism: read the Jailbreak 1.0 paper and the Assessment Standard, review the public Safety results, and see the AI Reliability Map, which outlines the benchmarks still to be built and welcomes your input.