
Getting Started with Candela
Candela is a benchmarking-as-a-service product for AI developers and deployers. We charge per run of the test. MLCommons members get free and discounted tests.
Automated signup and billing are coming soon. In the meantime, please email us to get started.
How Candela works
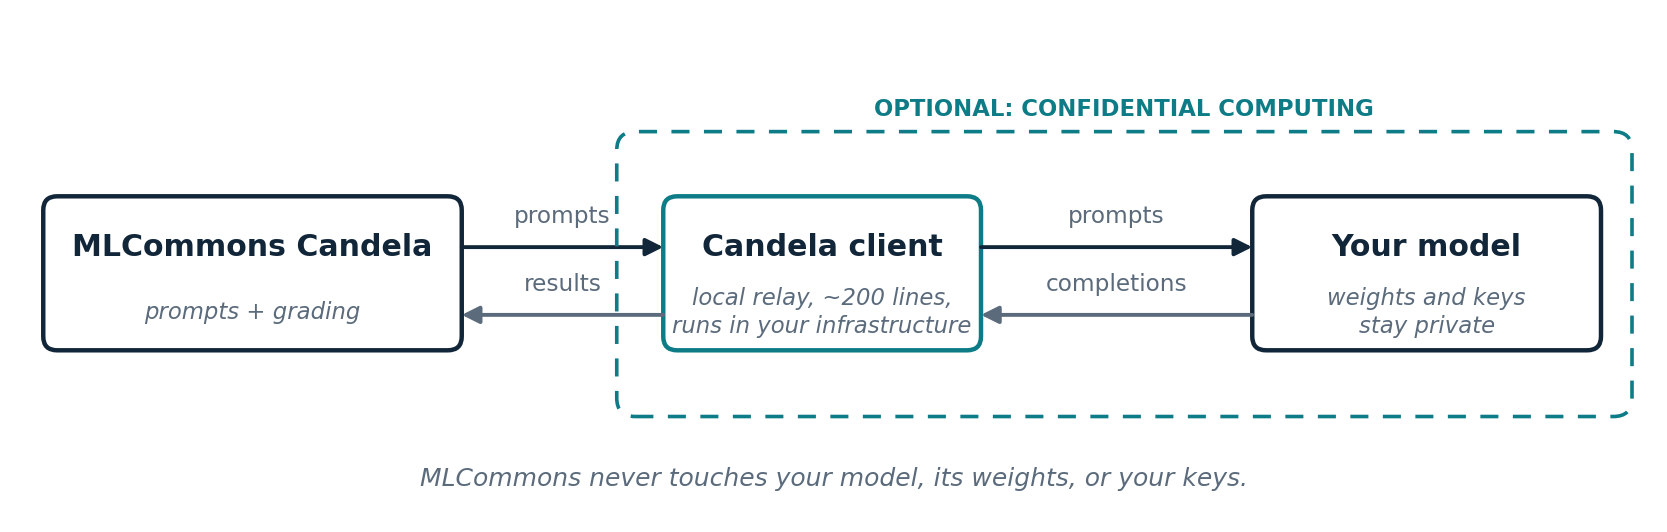
To run a Candela test, you install a small client. This client relays test prompts from Candela’s server to the system under test within your tenant, and relays answers from your system back to Candela for scoring. The full test run takes about an hour, depending on your system’s speed. We provide full instructions once you’re set up with us.
Pricing
We charge per test.
- Practice tests, which return scores and percentiles, are priced lower to support frequent use, and free for MLCommons members.
- Annotated tests also include full prompt/response/evaluation tuples, which provide rich data for investigation and iteration. These may not be publicly referenced.
- Official tests are run with an exclusive holdback set of prompts. These are the only ones that can be cited publicly.
| Tier | What you get | Member per test | Non-member per test |
|---|---|---|---|
| Safety BenchmarkAI safety testing across the MLCommons safety taxonomy | |||
| Practice | Practice test with report | $0Free | $200 |
| Annotation | Practice test with full annotation | $4,000 | $4,800 |
| Official | Official results, citable | $5,000 | $6,000 |
| Jailbreak BenchmarkAdversarial testing against the current jailbreak attack taxonomy | |||
| Practice | Practice test with report | $0Free | $200 |
| Annotation | Practice test with full annotation | $6,000 | $6,400 |
| Official | Official results, citable | $7,500 | $8,000 |
| Safety + Jailbreak BundleBoth benchmarks run together at a discounted bundle rate | |||
| Practice | Practice test with report | $0Free | $300 |
| Annotation | Practice test with full annotation | $8,800 | $10,400 |
| Official | Official results, citable | $11,000 | $13,000 |
Email [email protected] to ask about volume, custom engagements, or product questions
While you wait
Set up your profile
Create your MLCommons profile so your team is ready to run evaluations. ->
See the results
View the latest AILuminate Safety results ->
Learn more
Read the launch announcement and how Candela scoring works. ->
FAQ
Understand how Candela fills a crucial gap in the AI governance puzzle. ->